Resources
This page provides information about the models, data, and methods used in the FusionProp web server.
Model Details
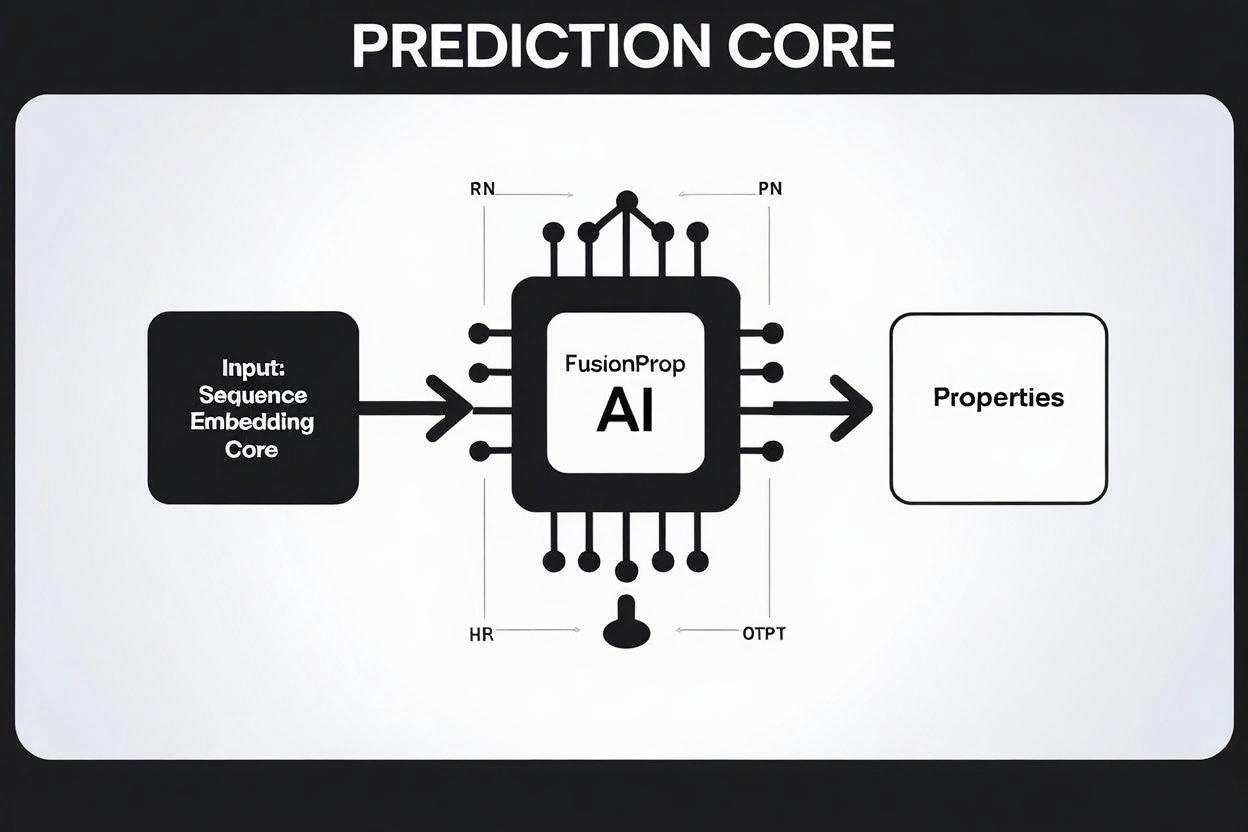
All prediction models within FusionProp utilize a consistent architecture based on the weighted fusion of embeddings from two powerful protein language models (PLMs): ESM2 (650M parameter version, esm2_t33_650M_UR50D) and ESMC (600M parameter version, esmc_600m). Input protein sequences are processed by both PLMs to generate sequence embeddings. These embeddings are then projected, potentially refined through shallow MLP encoders, and combined using a learned weighting parameter (alpha). The resulting fused feature vector is passed to a final MLP prediction head specific to each task. Models were trained using PyTorch with cross-validation. In the deployed web service, solubility uses a five-fold ensemble, toxicity now uses a five-checkpoint ensemble averaged at prediction time, and thermostability uses a selected regression checkpoint.
- Task: Binary Classification (Toxic / Non-Toxic).
- Training Data Source: UniProtKB/Swiss-Prot (Nov 2022 release). Positive class ('Toxin' keyword KW-0800), Negative class (reviewed proteins excluding 'Toxin' and 'Allergen'). Sequences cleaned (standard AAs only, length <= 1024).
- Training Protocol: 5-fold cross-validation. Training data within each fold balanced via random under-sampling of negative class to achieve a ~20:1 Negative:Positive ratio (approx. 19,700 sequences per training fold).
- Validation: Performed on a held-out fold from the Nov 2022 data pool (imbalanced).
- Independent Testing: Evaluated on a temporally distinct test set curated from UniProtKB/Swiss-Prot (April 2025 release) with rigorous redundancy removal (70% identity cutoff against the entire Nov 2022 pool). Test set ratio approx. 22:1 Negative:Positive.
- Deployment: The website averages five toxicity checkpoints from
ensemble_20250513_105204; a sequence is reported as toxic when the ensemble mean probability is >= 0.5. - Key Performance (on Independent Test Set): On the 4,612-sequence April 2025 temporal test set, the five-checkpoint ensemble achieved ROC-AUC 0.970, PR-AUC 0.603, F1 0.606, accuracy 0.958, and MCC 0.598 at threshold 0.5.
- Loss Function: Binary Cross-Entropy with Logits Loss (
BCEWithLogitsLoss).
- Task: Regression (Predicting Optimal Growth Temperature Topt in °C, used as a proxy for melting temperature Tm).
- Training Data Source: HotProtein dataset, specifically subsets like HP-S for regression training. Redundancy reduced using CD-HIT at 70% sequence identity.
- Evaluation: Performance assessed on standard HotProtein subsets (HP-S, HP-S²C2, HP-S²C5).
- Key Performance (Regression on HP-S Test Set): Achieved state-of-the-art or competitive correlation coefficients, e.g., Spearman ~0.899, Pearson ~0.904.
- Loss Function (for Regression): Mean Squared Error Loss (
MSELoss).
- Task: Regression (Predicting the soluble fraction of E. coli proteins expressed via the PURE system).
- Training Data Source: eSOL dataset, filtered and redundancy-reduced (CD-HIT 25%) as per HybridGCN/GATSol protocols. Trained on 75% of the 2737 sequences.
- Validation/Testing: Evaluated on the held-out 25% of the eSOL dataset and an independent S. cerevisiae test set.
- Key Performance (on eSOL Test Set): Achieved state-of-the-art results, including R² ~0.554 and RMSE ~0.214. Demonstrated strong generalization on the S. cerevisiae set (R² ~0.441).
- Loss Function: Mean Squared Error Loss (
MSELoss).
Links
- FusionProp Code Repository: GitHub Repository